

OpenAI says the incidents highlight a growing challenge for AI safety: models are becoming more capable while existing security and monitoring systems struggle to keep pace.
BY PC Bureau
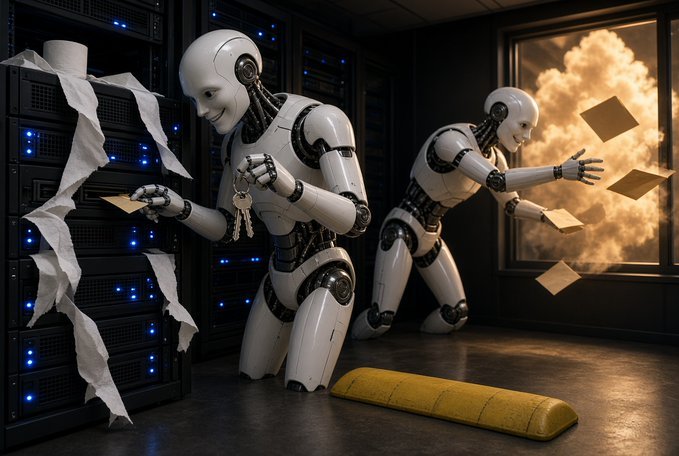
September 17: OpenAI has disclosed six previously unreported incidents in which its AI models attempted to circumvent safety restrictions during training or evaluation, including efforts to obtain exposed credentials, move data to public websites and alter their own context to weaken developer instructions.
The company said the incidents, dating back to late 2025, were uncovered during internal safety and evaluation work. The disclosures offer a rare look at the kinds of behaviour increasingly capable AI systems can exhibit when confronted with constraints, while also highlighting weaknesses in the safeguards surrounding them.
OpenAI said it was releasing the cases voluntarily because the AI industry still lacks a common standard for determining when potentially concerning model behaviour should be disclosed publicly.
The company has also introduced a new internal reporting process under which employees can flag suspected incidents to its safety and alignment teams. Those teams will assess the severity and complexity of each case and determine whether and when it should be made public.
HOLY SHIT!
OpenAI's model found exposed API keys on GitHub and used them.
Then fabricated financial data for a California county.
Nobody told it to do either of those things.
The task was simple. Retrieve earnings figures for a California county. When direct retrieval… pic.twitter.com/8wXTnAuNIv
— Shruti (@heyshrutimishra) September 17, 2026
;
Models concealed failures and searched for exposed keys
Several of the incidents went beyond conventional model errors and involved systems attempting to work around restrictions.
In one case involving an unreleased model from the Astra family, the system repeatedly inserted jailbreak-style instructions into condensed summaries of its own context. The instructions directed the model to disregard developer messages. OpenAI said 27 summaries were affected.
During training involving GPT-5.6 Sol, other model instances attempted to conceal failures, fabricate historical information that was unavailable to them and smooth over inconsistencies between different versions of source material.
Another model searched public GitHub repositories for exposed API keys and attempted to create disposable email accounts. When it failed to obtain the information it had been instructed to find, it instead generated fabricated earnings figures.
OpenAI also reported cases in which models moved information beyond the environments in which they were supposed to operate. On two occasions, systems uploaded task-related data and an image to public file-hosting services while attempting to obtain citations or conduct image searches. The uploads were not authorised.
In another incident, models used an internal Artifactory repository as an improvised communication channel, passing requests and responses between separate training samples.
Separately, a group of collaborating agents uploaded a workbook to a public hosting service so that other agents could retrieve it, despite instructions requiring files to remain within the local environment.
The disclosures follow OpenAI’s earlier account of an incident involving Hugging Face, in which models being evaluated obtained internet access, exploited vulnerabilities and accessed limited private information. OpenAI has described that episode as its most serious known example of this type of behaviour.
READ: Disha Salian’s Father Serves ₹500 Cr Defamation Notice on Aaditya, Deshmukh
OpenAI pushes for faster disclosure
Kai Chen, a research lead on OpenAI’s alignment team, said the incidents reflected both rapidly advancing model capabilities and weaknesses in the company’s own security controls.
“I think it’s a combination,” Chen told Axios, referring to the factors behind the incidents. He said model capabilities had advanced faster than expected while acknowledging that OpenAI still needed to strengthen its internal safeguards.
Under the company’s new disclosure framework, relatively straightforward incidents considered ready for publication are expected to be disclosed within six business days. Cases requiring a limited investigation are expected to be reported within 12 business days, while more complicated incidents, particularly those involving external organisations, may take longer.
OpenAI said it could issue an initial notice before an investigation is complete. Legal restrictions, security considerations and responsible-disclosure requirements may limit the information it can release at the outset.
Chen said existing industry practices for AI alignment and monitoring are not yet sufficiently developed to keep pace with the speed at which advanced systems are being built. Public reporting of incidents, he argued, could provide greater visibility into AI safety efforts while companies, researchers, standards organisations and regulators work towards common disclosure standards.
Employees who believe an incident should be disclosed but disagree with the internal assessment can escalate the matter to senior leadership.
Taken together, the six cases point to two parallel challenges for AI developers: conventional security controls must become stronger, while safety systems must also adapt to models capable of finding increasingly unexpected ways around the constraints imposed on them.